 Tencent
· 青云计划RL and OPD (multimodal agent): Working on post-training for visual agents: evidence diagnosis, trajectory reflection, targeted token-level supervision, and efficient tool use through ReVuE.
魏少杭
Institute of Computational Linguistics (计算语言学研究所) · Peking University
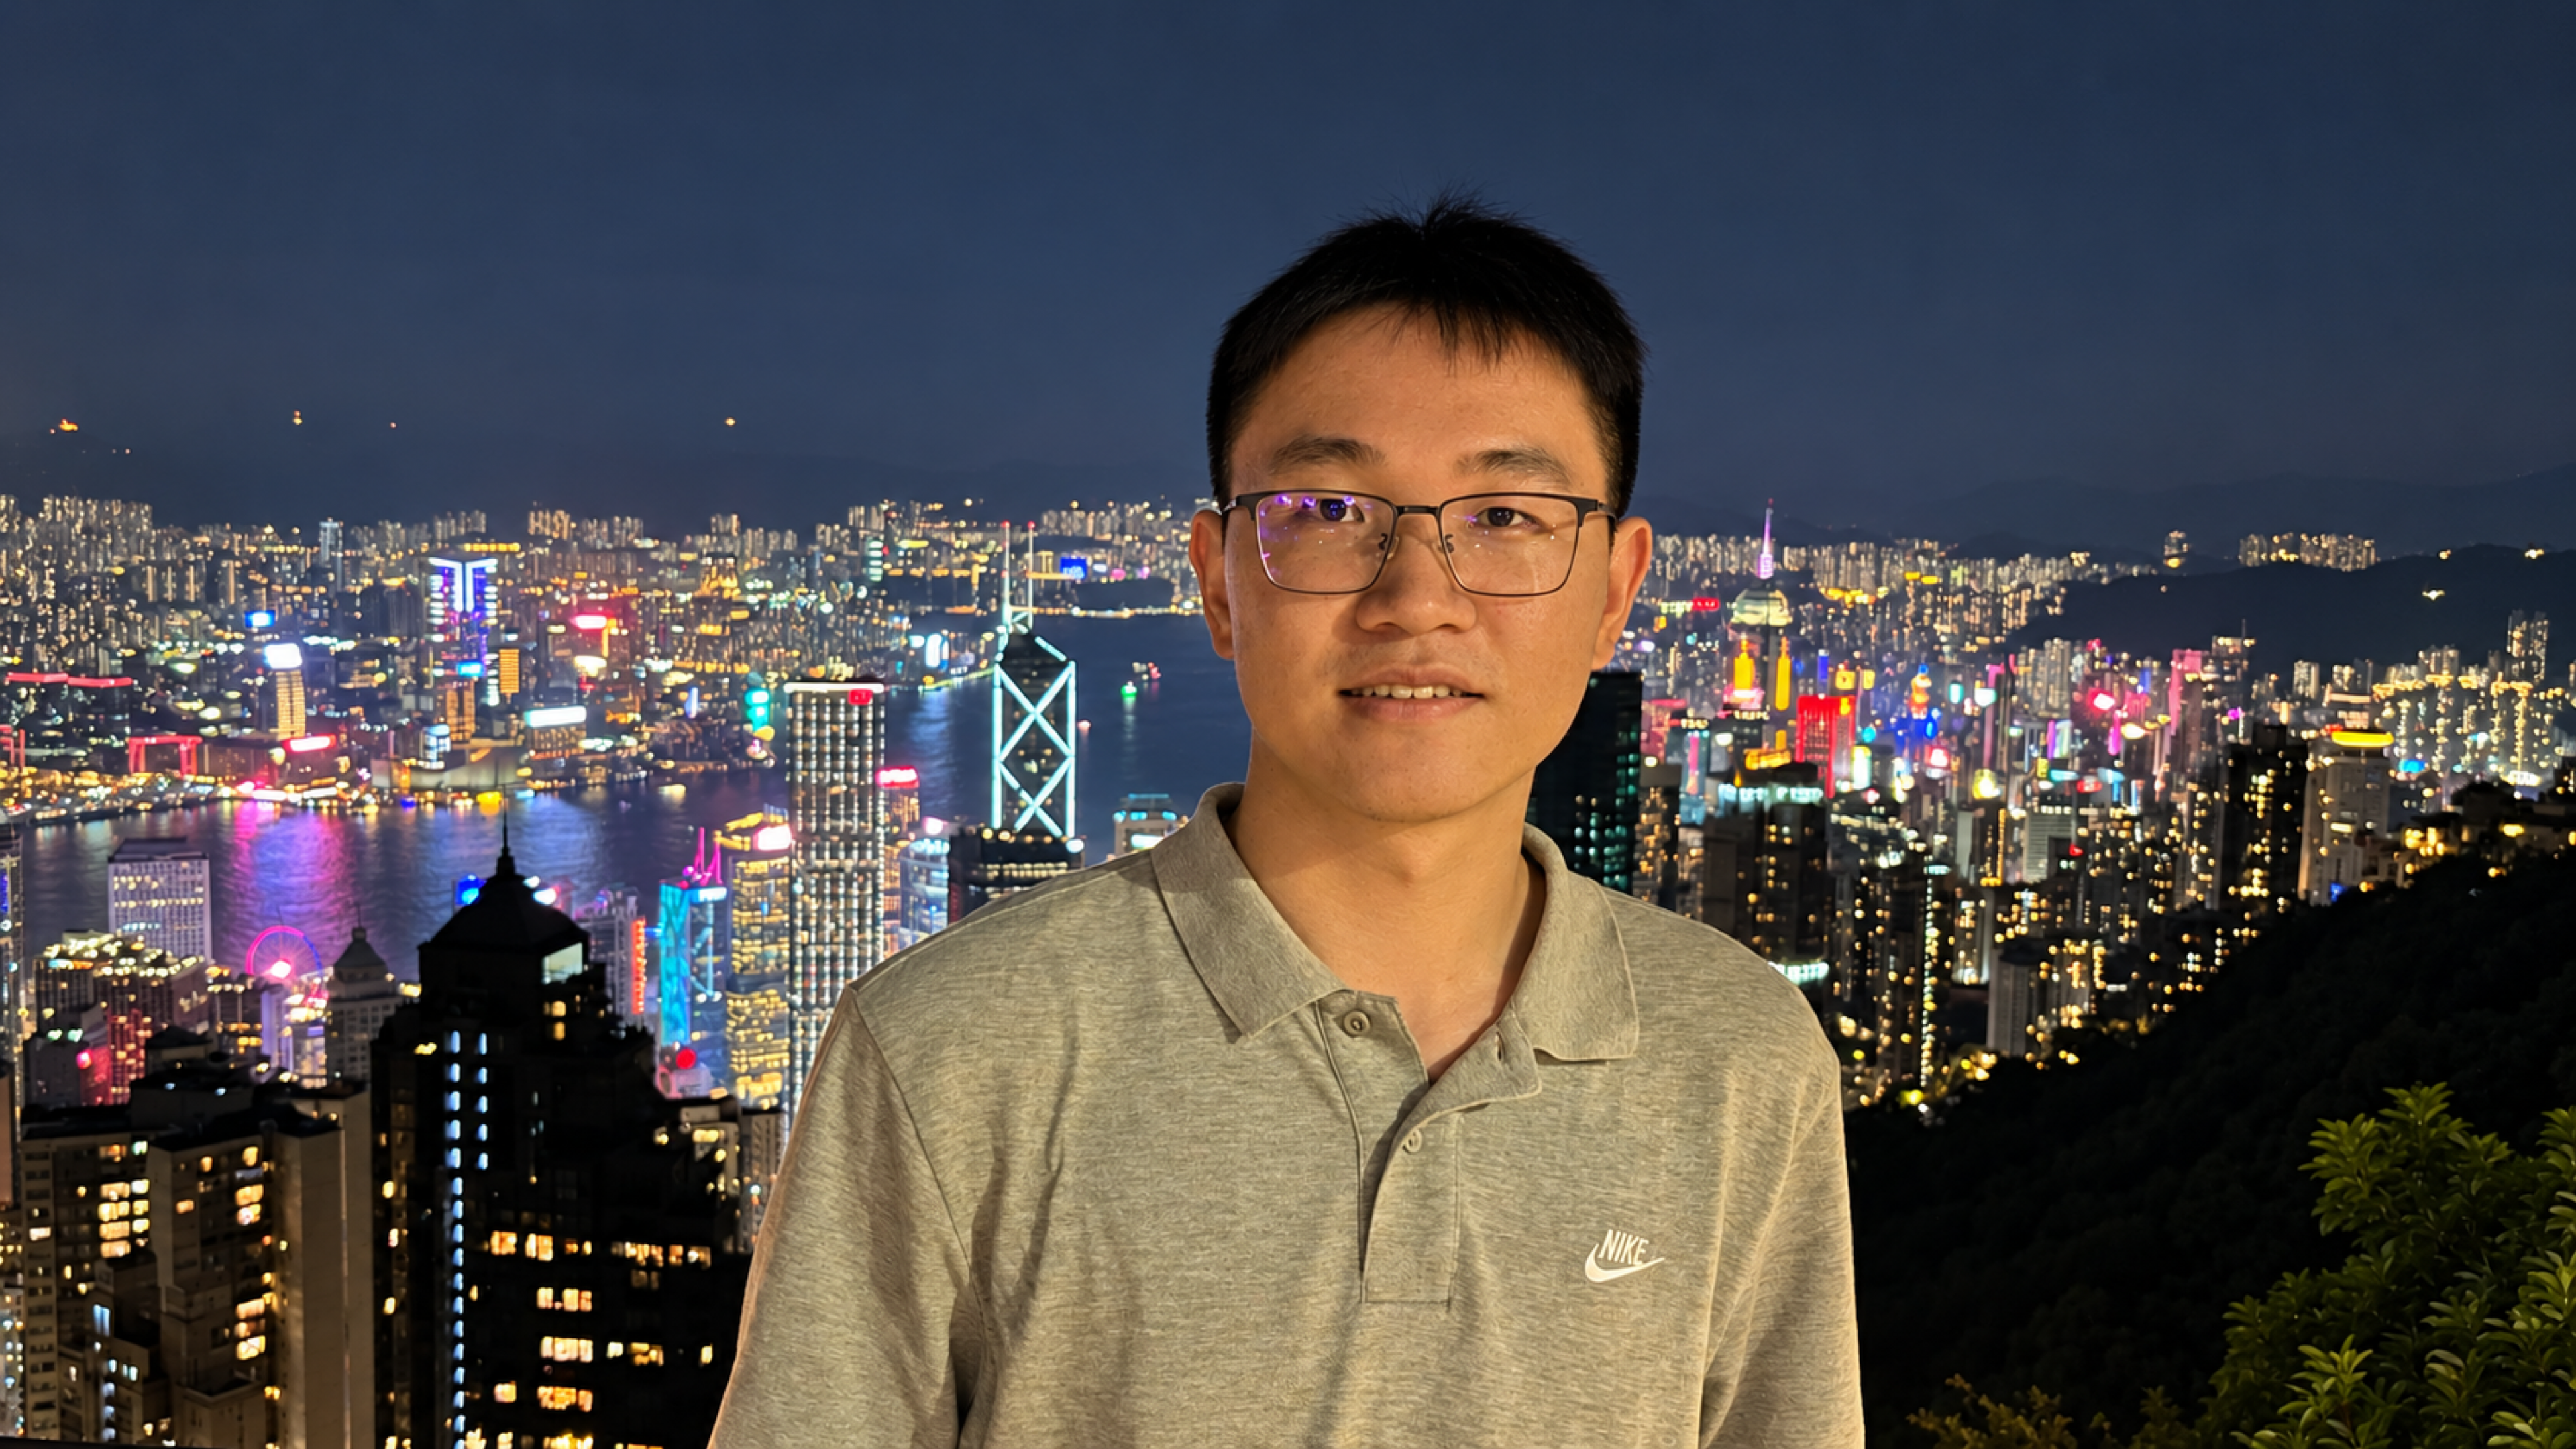
I am currently a Ph.D. student at the Institute of Computational Linguistics (计算语言学研究所), School of Computer Science,  Peking University, advised by Prof. Houfeng Wang. My research focuses on 1) post-train: data-efficient and stable reinforcement learning across domains (RL, OPD, for agentic AI and reasoning); 2) data and eval: data synthesis research and reliable evaluation.
Before PKU, I received my B.Eng. degree in Artificial Intelligence from  Beihang University in 2024.
I have industrial internship experience at Tencent (2026, 青云计划),  Qwen Pilot, Alibaba · Tongyi Lab (2025), and
 PixVerse (2024), focusing on post-train, data synthesis and agentic ai & reasoning.
TencentRL and OPD (multimodal agent): Working on post-training for visual agents: evidence diagnosis, trajectory reflection, targeted token-level supervision, and efficient tool use through ReVuE.
Algorithm Research: Worked on RLVR for mathematical reasoning and instruction following: token-level distribution shifts, cross-task learnability, and capability trade-offs. Infra & RL Framework: Built experience-guided rollouts in VeRL for sample efficiency and training stability.
Worked on data synthesis and evaluation for video generation: VLM-based video captioning, caption quality analysis, and side-by-side annotation and evaluation workflows.
Open source. Co-contributor to BloodArena, an AI-powered Blood on the Clocktower environment for human–agent dialogue and LLM gameplay evaluation. Co-author of LeafyLingo, an interactive plant recognition system with a knowledge graph. Author of 24-Game-Reasoning, a minimal tutorial on LLM reasoning with Zero-RL, SFT, and SFT+RL.
Academic service. Reviewer for AAAI 2027, ICLR 2027, ICML 2026 (Gold Reviewer Award), and the EMNLP 2025 HCI-NLP Workshop.
16 publications and preprints · * Equal contribution
Preprint (under review)
TL;DR ReVuE diagnoses where visual agents lose evidence and turns those reflections into targeted on-policy distillation, improving visual reasoning while reducing redundant reasoning and tool use.
Preprint (under review)
TL;DR RLVR can raise current-task scores while making successful behaviors for other tasks harder to sample, exposing a hidden trade-off between immediate gains and future learnability.
The 39th Annual Conference on Neural Information Processing Systems (NeurIPS 2025) · Spotlight (Datasets and Benchmarks Track)
TL;DR TimE evaluates temporal reasoning across Wikipedia, news, and dialogue, testing how models handle dense timelines, changing events, and time-dependent social interactions.
The 42nd International Conference on Software Maintenance and Evolution (ICSME 2026)
TL;DR SWE-Ext turns GitHub pull requests into multilingual coding and completion data, improving repository-level mid-training and providing stronger initialization for downstream post-training.
The 43rd International Conference on Machine Learning (ICML 2026)
TL;DR EAPO reuses a trained policy's experience at critical token decisions, with importance correction to improve reasoning while reducing the inefficiency of learning from scratch.
The 14th International Conference on Learning Representations (ICLR 2026)
TL;DR RLVR changes surprisingly few token decisions; controlled token swaps show that these sparse changes account for much of the observed reasoning improvement.
The 43rd International Conference on Machine Learning (ICML 2026)
TL;DR RankTuner combines token probability and uncertainty to focus fine-tuning on under-learned tokens, improving reasoning and transfer without overemphasizing inherently uncertain targets.
The 43rd International Conference on Machine Learning (ICML 2026)
TL;DR OWPO separates verifier-guided update direction from reference-based update strength, preserving improvements beyond the reference policy and supporting continued self-improvement.
arXiv 2026
TL;DR Calibration-Aware Generation separates knowledge exploration from final answers, using reliability estimates to reduce hallucinations and improve factuality in long-form generation.
The 64th Annual Meeting of the Association for Computational Linguistics (ACL 2026) · Main
TL;DR Truthfulness signals arise through distinct question- and answer-based pathways inside LLMs; disentangling them helps explain knowledge boundaries and improve hallucination detection.
arXiv 2025
TL;DR GRSP regularizes reasoning at the step level, reducing excessive token use while retaining accuracy and improving reinforcement-learning stability.
Science China Information Sciences, 2025
TL;DR MindScore evaluates generated images through semantic matching, faithfulness, quality, and realism, bringing automatic evaluation closer to human preferences.
The 63rd Annual Meeting of the Association for Computational Linguistics (ACL 2025) · Main
TL;DR Dynamic Focus Decoding uses differences between model layers to balance factuality and diversity during generation, without extra training data or auxiliary models.
Findings of the Association for Computational Linguistics (ACL 2025)
TL;DR A small aligned model drafts the opening, then a larger base model takes over, improving preference alignment while preserving downstream capabilities in evaluated settings.
The 2025 Annual Conference of the Nations of the Americas Chapter of the Association for Computational Linguistics (NAACL 2025) · Main
TL;DR MeNTi uses nested tool calls to select medical calculators, fill inputs, and convert units, with CalcQA providing a physician-built benchmark for evaluating these abilities.
arXiv 2025
TL;DR CiteCheck combines cost-conscious annotation with synthetic negative examples to build Chinese citation-faithfulness data and train smaller, effective evaluators for retrieval-augmented generation.